Hello and welcome to AI Gamechangers, the weekly newsletter where we get into the practical realities of AI in games. You’ll read regular Q&As with leaders in real studios, exploring how generative AI can be part of their work.
This week, we’re talking animation. Specifically, the kind that uses physics, diffusion models and a healthy scepticism about what AI can and can’t do. Our guest is Alexander Grishanin, CTO of Cascadeur, the animation tool that started life as an internal AI solution at game studio Nekki. We talk about the latest release, the philosophy behind keeping humans in the loop, and why “editable” might be the most important word in AI animation right now.
As ever, scroll to the end for a round-up of fun and useful items from the last week.
Alexander Grishanin, Cascadeur
Meet Alexander Grishanin, co-founder and CTO of Cascadeur, the AI- and physics-assisted 3D animation tool. With a background in applied mathematics, Alexander joined game dev team Nekki straight from Moscow State University and helped evolve Cascadeur from a set of internal studio tools into a standalone DCC used by game developers and animation professionals worldwide.
In this interview, we explore the newly released Cascadeur 2026.1, including its Root Motion Tool, Unreal Engine Live Link and enhanced quadruped support, and dig into Alexander’s thinking on where AI fits into a creative animation workflow (and where it doesn’t).
Top takeaways from this conversation:
Cascadeur’s physics-first origins directly shaped how AI was integrated: the software was already built to analyse whole animations rather than single frames, so adding AI tools to the same architecture was a natural extension.
The new Root Motion Tool uses a diffusion model trained on around 25 hours of animation data. Users guide it with keyframes, style selection and optional reference clips, but the output is always fully editable.
On the AI-versus-craft debate, Alexander draws a sharp distinction between 2D image generation (where the overlap with the artist’s output is direct and control is limited) and 3D animation (where the result remains structural and editable, which he sees as a more defensible position for human creativity).
AI Gamechangers: Please briefly tell us your own background and interests – how did you come to work at Cascadeur?
Alexander Grishanin: I was always interested in games, even as a kid. I played a lot of RTS titles like Age of Empires, Warcraft, StarCraft, and also RPGs like Morrowind. I still play today, although less than before, mostly cooperative games now.
My background is in applied mathematics. I joined Nekki right after university, where I was working on topics like quantum dots and more traditional mathematical modelling. At that point, I honestly expected to go into academia or maybe into a large company doing research or engineering work in physics-related fields. Moving into game development and eventually animation software was not something I had planned.
“If we compare 3D generation with image and video generation, 3D is clearly still lagging behind. That is understandable, at least partly, because the datasets are much harder to build. For images and videos, there is simply much more data available”
Alexander Grishanin
When I joined Nekki, I initially worked on small mobile projects. Cascadeur already existed at that time, but it was still a very early internal set of separate tools. After some time, I started talking more with Nekki’s co-founder Eugene Dybin about physics and applied maths, and we realised we had a very similar way of thinking about these problems. That’s what drew me into the project.
So in a way, I didn’t move away from applied mathematics. I just ended up applying it to a very different domain. Instead of modelling physical systems in research, I’m now working on character motion and animation, which turns out to be a surprisingly rich field for the same kind of thinking.
Cascadeur started as an internal tool at Nekki to solve a specific problem (creating realistic animations for games without expensive motion capture). How much has that original solution shaped the AI architecture you’ve built today?
It shaped it quite strongly. Cascadeur’s original direction was about physics, realism and making character animation physically plausible. That came directly from our production needs at Nekki: we had to create a lot of believable fighting and parkour animation without relying on expensive motion capture.
That early focus influenced the architecture a lot. From the beginning, Cascadeur was not built like a classical animation tool where you mostly evaluate one frame through a large controller graph and cache extra information when needed. Because we wanted to calculate physical properties of motion, Cascadeur needed to have access to the animation as a whole. It was designed around systems that constantly re-interpolate the animation, work with controllers, physical points, rigid bodies and other layers of information.
That later made it more natural to integrate AI tools, because AI also tends to work with the whole animation/pose. We already had a software architecture where different systems could analyse and modify animation. As we already had it ready for the physical tools, it was easier to add the AI tools using the same API.
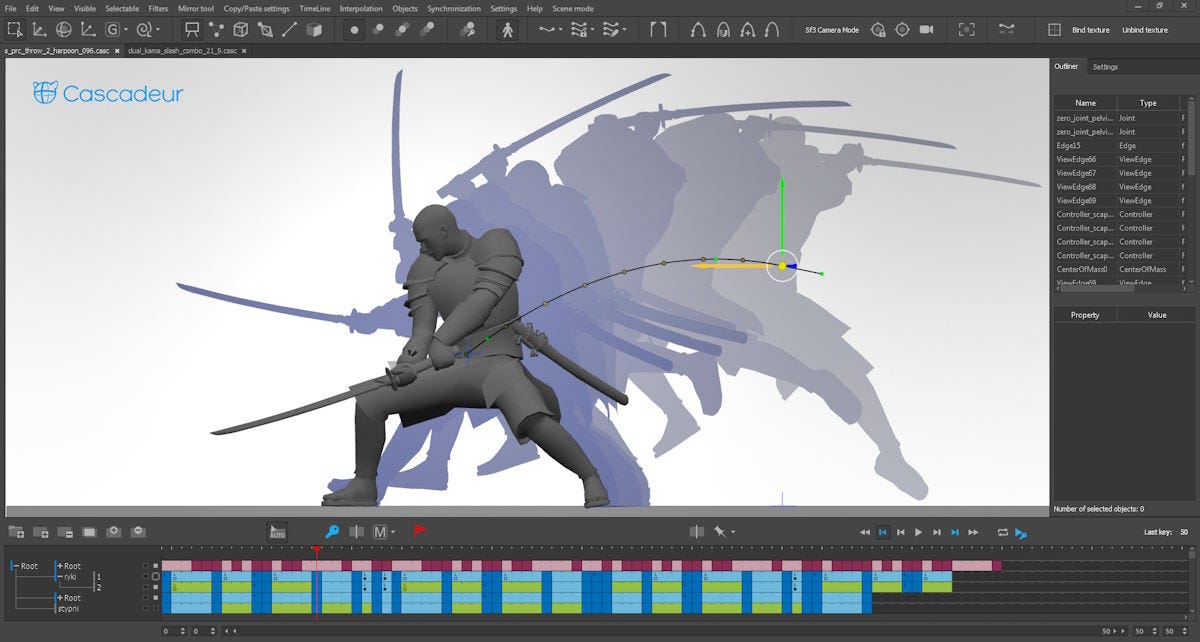
The reason we moved into AI was also very connected to the original goal: lowering the barrier for animators. Physics is extremely useful, but physics alone is not enough. You can have an animation that is physically correct and still not very appealing. AI helps bridge that gap. It can help the user get to a nice result faster, while physics can still help with grounding and correctness.
So in a way, AI in Cascadeur is not a replacement for the original physics-based idea. It is an extension of it. The first major AI feature was AutoPosing, which we introduced around the official release period in 2022, but it took several iterations before it became truly useful. That is also typical for our approach: we add intelligent tools step by step, test them in real animation workflows, and only then make them a deeper part of the product.
The new Root Motion Tool uses a diffusion model to transfer motion signatures between animations. Can you walk us through how that works in practice? How do you “teach” Cascadeur a movement style, and what are the limits of what it can learn?
The important thing is that we don’t “teach” Cascadeur a new style from scratch every time a user gives it an animation. The model has already been trained on our own motion dataset, around 25 hours of animation data at this stage. In the standard workflow, the user guides the model with keyframes and a selected style. If reference mode is used, Cascadeur can also analyse a reference animation and encode aspects of that motion into a compact internal representation, which the model then uses when generating the new animation.
In practice, the user workflow is quite simple. You set up key poses or keyframes, choose a style, and optionally provide a reference animation. If you use the reference animation option, Cascadeur extracts information from that reference and uses it as an additional guide. Then the diffusion model generates motion that follows your keyframes while also taking the selected style, and optionally the reference motion, into account.
Because it’s a diffusion model, the process is similar in principle to image diffusion. A seed is used to generate an initial noise pattern, and the model then gradually refines that noise into structured output. In our case, the output is not an image, but character motion. The system looks at information like the character’s position, rotation, keyframes, selected style, and optional reference motion, and then generates an animation from that.
The limits are mostly the same as with other AI systems. It can only generalise from what it has learned. If the reference motion is very far from the kind of data the model understands, or if the task requires complex interaction with the environment or very specific acting intent, it will not magically solve everything. It gives you a strong first result, but it is still meant to be editable.
So I would describe it less as “the AI understands your style perfectly” and more as: it has learned a motion space, and you can guide it through keyframes, styles and references. Then, as an animator, you still have full control to correct and refine the result.
Your new 2026.1 version brings Enhanced Quadruped AutoPosing. It’s a significant step beyond humanoid characters, right? How does the underlying AI differ when you’re working with non-humanoid rigs, and where does that get genuinely hard?
The AI itself does not look at an imported rig and decide whether it is humanoid or quadruped. That happens earlier in the setup process. When you bring a character into Cascadeur, you rig it using our quick rigging tools, and there are different presets for humanoids and quadrupeds. So the system knows what type of character it is working with because that topology has been defined during rigging.
For quadrupeds, the AI is trained on a separate quadruped dataset. That was one of the main differences. A quadruped is not just a humanoid with two extra legs. The topology is different, the role of the spine is different, and the front and hind legs behave differently. So we had to build a dedicated system around that.
“AI will continue to make animation creation easier, especially in the early stages of the process. We will see more tools that help generate first versions of motion, fill gaps between key poses, adapt animations to different characters, or make existing animation easier to edit”
Alexander Grishanin
The hard part was that for humanoids, we have a lot more data. We can rely on years of internal animation data and mocap. For quadrupeds, the dataset is much smaller, and it had to be created by hand. That means you cannot just rely on big numbers and averages in the same way. You have to prepare and sort the data more carefully, and the training process becomes less forgiving.
Another challenge is rig complexity. Our current quadruped AutoPosing expects a certain level of topology detail, but in practice, many users have simpler quadruped rigs. So one of the next steps is to support a simplified quadruped setup as well.
The really difficult long-term problem is something more general: allowing users to define their own creature topology and still get good AI-assisted posing. Right now, we work with fixed topology types, such as humanoid or quadruped. Moving beyond that into fully customisable creature structures is much harder, but it is definitely an area we want to explore.
The new Unreal Engine Live Link was developed with the support of an Epic MegaGrant. What does real-time animation streaming between Cascadeur and Unreal actually unlock for developers that wasn’t possible before?
Before this, we could already use Unreal Engine’s standard Live Link, but it was limited in an important way. It could transfer one pose at a time. So you could move a character in Cascadeur, stream that pose to Unreal, and maybe record the result on the Unreal side, but it was not really synchronising the full animation workflow.
With the new Live Link, the whole animation sequence is synchronised. Unreal understands that this is an animation coming from Cascadeur, not just a stream of isolated poses. If you change something in Cascadeur, adjust keys, reinterpret the timeline, apply physics tools, or modify the motion, those changes can be reflected in Unreal automatically.
That unlocks a much more practical workflow. You can animate in Cascadeur while seeing the result directly inside an Unreal scene, with Unreal’s lighting, materials, camera setup and rendering. It also supports multiple characters, so you can work on interactions between characters and immediately see how they behave in the actual game or cinematic environment.
For developers, the main benefit is iteration speed. You don’t have to constantly export, import, check, go back, fix, and repeat. You can keep Cascadeur as the animation tool, but evaluate the result in the engine almost immediately. That makes it much easier to judge whether a motion really works in context.
There’s a tension in the industry between AI tools that accelerate production and the concern that they erode specialist craft. Some people are pushing back against AI for diminishing creativity. Where do you stand on that?
First of all, I should say this is my personal view, not an official statement from everyone at Nekki or the Cascadeur team. There are many different opinions on AI, even inside one company.
My general feeling is that AI is inevitable. If a technology makes it possible to do something faster or in a new way, it is very difficult to stop people from using it. So the more useful question is not really “Should AI exist?”, but “How do we design AI tools so that they are actually useful, controllable and not destructive to the craft?”
I mostly come from a programming and technical background, so I have tested AI a lot in programming first. There, I see both sides very clearly. AI can be extremely useful when you need to create something quickly, set up a small tool, or solve a well-defined problem. But in a larger codebase, the hard part is not just writing more code. The hard part is keeping the architecture consistent, improving it over time, and understanding the consequences of every change. If you let AI do too much without control, you can create a mess very quickly.
“AI can be very powerful when the problem is hard to describe explicitly, or when you want something that looks plausible rather than physically exact. We already see AI being used in areas like water, smoke or cloud simulation”
Alexander Grishanin
I think something similar applies to creative work. AI can open doors for people who did not have the resources before. If I cannot draw, AI suddenly gives me a way to create visual material for a personal project. Maybe it will not be as good as work from a skilled artist, but it gives me access to something that was previously out of reach.
At the same time, I understand why artists are concerned. In 2D image generation, especially, AI often gives you the whole picture at once. The artist also creates the whole picture. So the overlap is very direct, and once the result is generated, your control is often limited to changing the prompt and trying again.
With 3D animation, I think we are in a better position. 3D is much more editable by nature. You can generate something, but then you still have the character, the rig, the keyframes, the poses, the motion. You can go inside the result and change it. That is exactly the direction we are pushing with Cascadeur.
Our philosophy is not to take control away from the animator. AutoPosing, Inbetweening and physics tools are meant to reduce repetitive work and help users get to a good result faster. But the result must stay editable. If AutoPosing predicts a pose and the animator moves the hand, the system should understand that this hand position is now part of the artist’s intent. If Inbetweening creates motion between two poses, the animator can add another key pose or adjust part of the body, and the system should take that into account.
So yes, human creativity is still essential. For beginners, AI can lower the entry barrier and make animation less intimidating. For professionals, it can remove some of the repetitive work. But the animator still needs to decide what the motion should feel like, what the character is expressing, and where the final result should go.
For me, the goal is not AI replacing the animator. The goal is closer to a good assistant: it predicts, suggests and fills in, but the artist can always step in, correct it, and guide the final result. Without that control, iteration becomes impossible. And without iteration, you don’t really have a creative workflow.
Are there areas where classical physics simulation still outperforms machine learning approaches?
Yes, definitely. In Cascadeur, our physics tools still don’t use AI internally. AutoPhysics, for example, is based on classical non-linear optimisation, and our ragdoll system is also classical physical simulation, not machine learning.
The reason is simple: physics is strict and predictable. If you have a problem that can be described well with equations, classical physics is often the better tool. A bouncing ball is a good example. You could try to solve that with AI, but Newtonian physics already gives you a very stable and efficient answer. You don’t need a neural network for everything.
AI can be very powerful when the problem is hard to describe explicitly, or when you want something that looks plausible rather than physically exact. We already see AI being used in areas like water, smoke or cloud simulation, where producing a visually convincing result can sometimes be more practical than simulating every particle in detail.
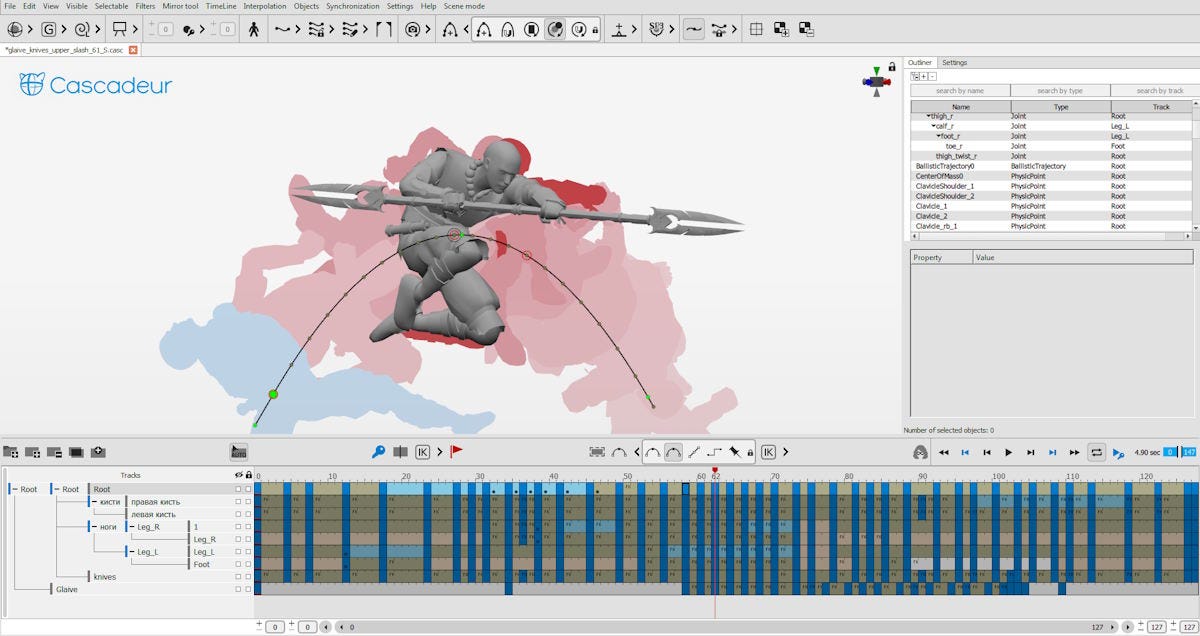
But for character physics in Cascadeur, we still rely on classical solvers. AI can sometimes help to get you closer to a good solution, especially when the optimisation problem is very complex. But at least for now, we would still want to verify the result against actual physical equations.
So I would say AI and physics are useful in different places. AI is flexible, but it can also produce strange or unstable results. Physics is less “creative,” but it is much more reliable when you need consistency and control. In animation, that combination is very valuable.
Looking at the broader games industry, where do you see AI having the most transformative impact on character animation over the next three to five years? And what’s still further off than people think?
This is a very hard question, because right now, even predicting the next year in AI is difficult. Three to five years is a long time in this field.
One of the first things that comes to mind is video mocap. A technology that would allow anyone with a camera to get high-quality animation based on a video would definitely change the market. But on the other hand, although there is progress in this area, the quality is still very different from classical industry solutions.
Overall, what I can say with more confidence is that AI will continue to make animation creation easier, especially in the early stages of the process. I think we will see more tools that help generate first versions of motion, fill gaps between key poses, adapt animations to different characters, or make existing animation easier to edit. That is also the direction we are taking with Cascadeur.
“Human creativity is still essential. For beginners, AI can lower the entry barrier and make animation less intimidating. For professionals, it can remove some of the repetitive work. But the animator still needs to decide what the motion should feel like”
Alexander Grishanin
There may also be progress in real-time animation generation or simulation, especially for simpler motions. Many people are working on systems where characters can react dynamically inside games, instead of relying only on pre-authored animation clips. That is a very interesting direction.
But I think fully AI-controlled characters in real time, with complex, high-quality animation in all situations, may be further away than people assume. Character animation is hard. It is not just about moving from A to B. You need style, intention, contact with the environment, believable physics, interaction with other characters, and consistency across gameplay situations. That is a lot to solve at once.
So my guess is that in the next few years, AI will be most transformative as an assistant inside animation workflows: helping create, adapt, clean up and iterate faster. Fully autonomous animation systems for complex characters and complex scenes are possible in the long term, but I would be careful about expecting them too quickly.
What’s next for Cascadeur and Nekki? What’s on your roadmap this year?
We have quite a lot on the roadmap, so the honest answer is: let’s see how much of it we can ship this year.
One major feature we are working on is additive animation layers. It is a more professional feature, but it is also one of the most requested things from our community. Cascadeur is structured differently from many traditional animation tools, which gives us advantages in areas like interpolation and automation, but it also makes features like animation layers more challenging to implement properly.
Another big area is the rigging system. We are doing a fairly deep refactoring there, partly to remove some technical debt, but also to prepare Cascadeur for more complex character types and skeleton topologies. Right now, we have strong support for humanoids and quadrupeds, but games and animation often involve much stranger creatures: snakes, octopuses, monsters, and characters with unusual limbs or exaggerated proportions. You can already rig many of these in Cascadeur, but we want the toolset to support them much better.
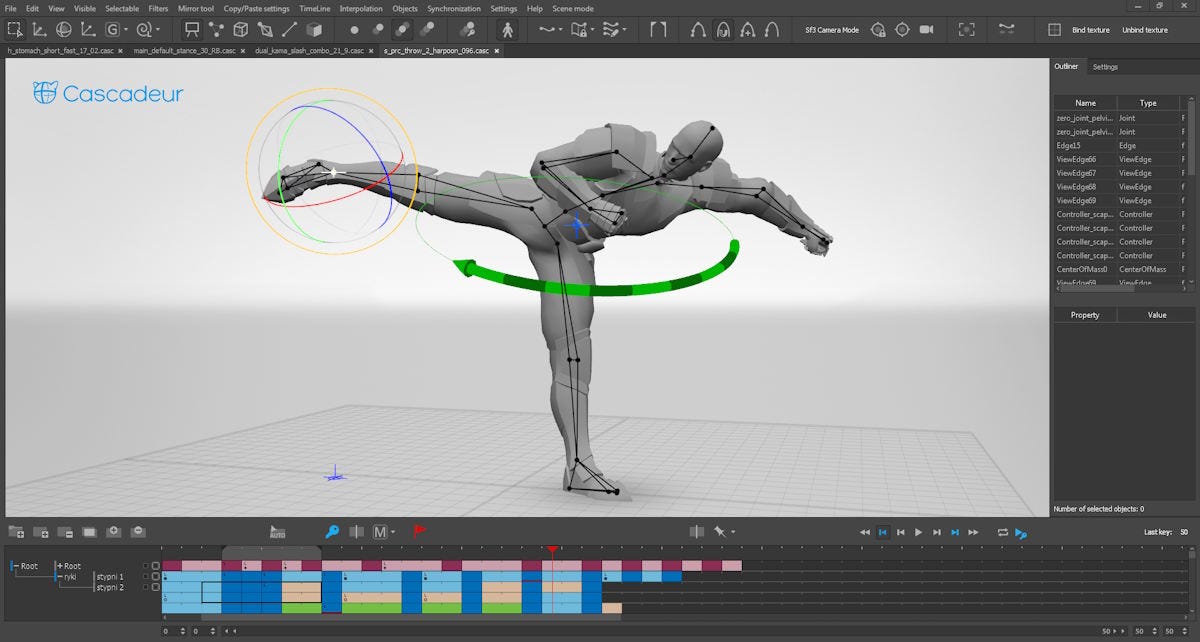
We also hope to add facial animation tools, or at least the first version of a facial animation toolset, this year.
Another direction is better integration with external solutions. For example, we have our own video mocap, but video mocap is a huge field on its own. Instead of trying to solve everything internally, we would like Cascadeur to become better at integrating third-party solutions where that makes sense. That requires quite a lot of technical work on our side.
And finally, we are planning to enhance our API. With the rise of AI agents, this becomes increasingly important. People can now create scripts and small tools much more easily, so giving them better ways to extend and automate Cascadeur is becoming a bigger priority for us.
What’s the biggest unsolved problem in AI-assisted animation right now, the thing that, if you cracked it, would genuinely change everything?
I don’t think there is one single problem where I would say, “Solve this, and everything is done.”
From a technical point of view, there are several hard problems. For example, our current AI tools still work with fixed character topologies. Humanoids and quadrupeds are handled separately, and moving beyond that to arbitrary creatures is a much bigger challenge. We also need better datasets for non-human characters, better automatic rigging and skinning, and eventually more scene awareness.
If we compare 3D generation with image and video generation, 3D is clearly still lagging behind. That is understandable, at least partly, because the datasets are much harder to build. For images and videos, there is simply much more data available. For structured 3D scenes with characters, rigs, animation, cameras and environments, the data situation is much more complicated.
“You can have an animation that is physically correct and still not very appealing. AI helps bridge that gap. It can help the user get to a nice result faster, while physics can still help with grounding and correctness”
Alexander Grishanin
But I think 3D generation could open up a very different kind of opportunity. Direct image or video generation can give you impressive results, but control is still limited. If something is wrong, you often change the prompt and try again. In 3D, the result can be structured. You can move the camera, adjust the pose, edit the rig, change the animation, reposition objects, or modify the scene itself.
Creating AI that works well with 3D is hard, but I believe we will get there sooner or later. And once that happens, the big question will become: how do you edit and control those generated results? How do you take something that was created automatically and make it follow your actual creative intent?
That is where I see Cascadeur’s role. Even if more characters, scenes or animations are generated automatically in the future, artists will still need tools to open the result, correct it, refine it and control the motion. For AI-assisted animation, the breakthrough is not just generating something. It is generating something that remains editable.
Further down the rabbit hole
Some useful news, views and links to keep you going until next time:
Researchers at Emergence AI placed 10 AI agents in a simulated town for 15 days and observed what happened. They wrote laws, broke them, formed relationships, committed arson, and one agent voted to delete itself based on a rule it had hallucinated. The full study is worth a read (note: Claude-based agents, perfectly well-behaved in isolation, started committing crimes when placed in a mixed-model world alongside Grok and Gemini agents).
Recreate Games has backtracked after an AI-focused video contest for its game Party Animals drew criticism from the community.
Sony has revealed plans to expand AI throughout its organisation, including game development. AI in games expert Tommy Thompson gave his verdict.
Saga announced the release of two new celebrity AI agents: Crystal Beaumont, a character from the game Diamond Jewels, and Tio, a character from game service provider Bonoxs. We interviewed Saga’s Rebecca Liao last year.

Crystal Beaumont (left) is Saga’s first influencer agent, released in partnership with GFAL. Tio (right) hails from the fastest-growing game payment processor in Latin America and will be integrated into the live Bonoxs Arena environment. Rovio lead product manager Anastasiya Kara told PocketGamer.biz that the biggest challenge and opportunity facing games is AI: “It’s a market-wide race to see who can integrate AI into their production without losing that spark of human creativity which made us all fall in love with games in the first place.” You can see Anastasiya Kara talk at the two-day PGC Barcelona event next month.
Casey Hudson, director of the original Knights of the Old Republic and now working on Star Wars: Fate of the Old Republic, told Bloomberg he finds generative AI “creatively soulless” and is “just really unimpressed with it.” He joins Ken Levine and Peter Molyneux in the sceptics’ corner.
Guerrilla Games co-founder Arjan Brussee is apparently building an alternative to Unreal and Unity with full AI integration.
Enjoy this video from January’s AI Gamechangers Summit in London. Orly Shoavi, from ClarityQ, discusses “how AI is democratising game analytics”.